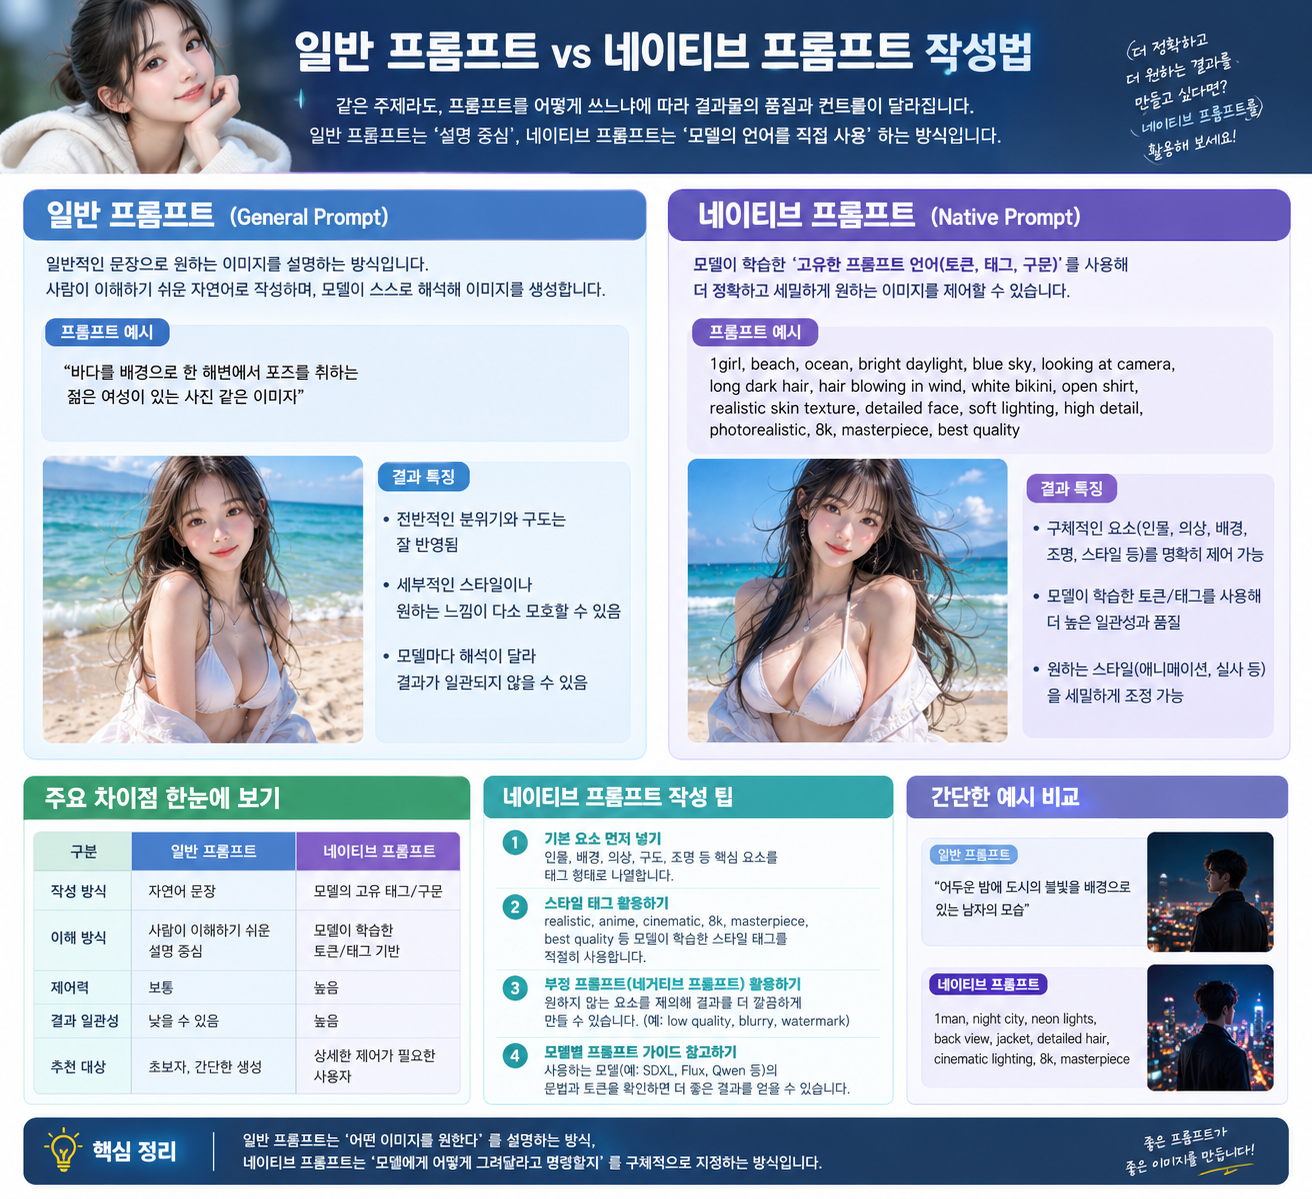
ComfyUI에서 Qwen Image 계열(예: qwen_image_2.1_int8_convrot) 모델을 다룰 때는 기존의 키워드 나열식 '일반 프롬프트'와 장면 및 관계를 서술하는 '네이티브 프롬프트'의 차이를 이해하고 적용하는 것이 생성 품질을 결정합니다.
| 비교 항목 | 일반 프롬프트 (태그 나열식) | 네이티브 프롬프트 (자연어 서술식) |
|---|---|---|
| 표현 형태 | 단어 및 쉼표(,) 기반 키워드 나열 | 문맥과 인과 관계가 담긴 자연어 문장 |
| 기반 텍스트 인코더 | 전통적인 CLIP Text Encode 계열 | Qwen2.5-VL 등 멀티모달 LLM 인코더 |
| 객체 간 상호작용 | 단순 존재 여부만 반영 (관계 왜곡 빈번) | 착용, 소지, 시선, 인과 관계의 정밀한 지정 |
| 공간 및 구도 배치 | 좌/우/배경 배치를 분리하기 어려움 | 좌우, 전후, 원근 배치를 문장으로 제어 가능 |
| 복잡한 장면 구현 | 요소가 많아질수록 혼선 및 블렌딩 발생 | 다단계 과정이나 복합 서사 묘사에 매우 유리 |
| Qwen Image 적합도 | 단순 객체 생성 시 활용 가능 | 모델 고유의 언어 이해력을 극대화하여 적극 권장 |
두 방식의 가장 결정적인 차이는 객체 간의 상호작용과 환경의 인과 관계를 모델에 어떻게 전달하느냐에 있습니다.
woman, red dress, city, night, umbrella, rain, neon lights모델은 단순히 '여자', '드레스', '도시', '우산'이라는 요소만 인지하므로 우산이 바닥에 놓이거나 네온 불빛이 엉뚱한 곳에 맺힐 수 있습니다.
A woman wearing a red dress stands on a rainy city street at night. She holds a transparent umbrella above her head while colorful neon signs reflect on the wet pavement around her.여성이 무엇을 입었는지, 우산을 어떻게 들고 있는지, 비와 바닥의 네온 반사가 어떤 환경을 만드는지 유기적으로 연결됩니다.
LLM, artificial intelligence, transformer, tokenization, neural network, self attention, embeddings, glowing data, futuristic laboratory, hologram, blue light, 3D render, cinematic, ultra detailed, realistic, 16:9Create a cinematic 3D visualization showing how an LLM processes a sentence.
On the left side, a sentence appears as glowing text and is gradually divided into individual tokens represented by small transparent luminous blocks.
The tokens flow into a large Transformer architecture where glowing lines connect related words via self-attention.
These tokens are transformed into high-dimensional vector representations visualized as clusters of luminous particles in semantic space.
Finally, the contextual representation flows toward the right side where the model predicts the next token.
The entire sequence clearly communicates: sentence → tokens → embeddings → self-attention → context → next token.
Futuristic AI laboratory environment, glass and metal materials, cinematic volumetric light, blue and cyan illumination, realistic reflections, 16:9.Qwen Image 계열 모델의 텍스트 인코더를 극대화하려면 다음의 계층적 구조에 맞춰 문장을 구성하는 것이 좋습니다.

Text Encoder Qwen Image 2.1 노드와 Qwen2.5-VL 텍스트 인코더가 올바르게 결합되어야 장문의 서술형 프롬프트가 온전히 해석됩니다.Qwen Image 모델은 거대언어모델(LLM) 기반의 텍스트 인코더를 탑재하고 있어 단순 단어 나열보다 문장 단위의 맥락과 공간 관계 묘사를 정밀하게 이해합니다. 프롬프트 작성 방식을 '키워드 조합'에서 '구체적인 장면과 동선 서술'로 전환하면 생성물의 완성도와 제어력을 극대화할 수 있습니다.

댓글목록
등록된 댓글이 없습니다.